
On this page3 sections
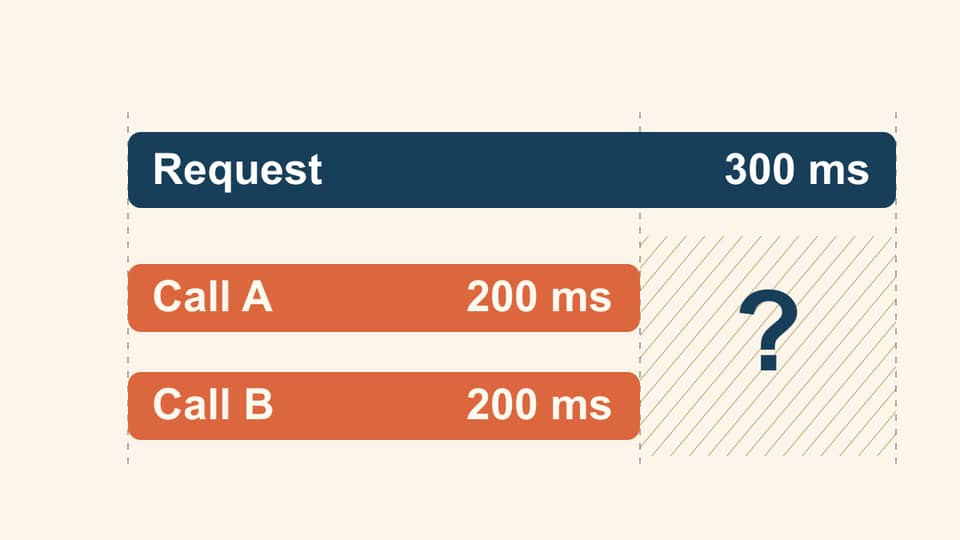
In this hypothetical trace, two calls take 200 milliseconds each. The request that made them finishes in 300. Both calls started together, so they use the same first 200 milliseconds. The next question is what kept the request open for the final 100.
A distributed trace connects recorded operations across a request. Start by lining up those operations on the same clock. The order and overlap tell you which part of the request to investigate, and the gaps tell you where you need another observation.
Read relationships before durations
A span records one operation, with start and end times and attributes that describe the work. A parent and child can be in different services. Span links can show related work that does not fit a parent-child tree, such as a worker processing messages from several requests. Passing trace context between services gives their instrumentation the identifiers to connect the records. The OpenTelemetry overview introduces the framework that applications use to produce this telemetry.

Read diagram description
Two calls start together and both finish at 200 ms. The parent ends at 300 ms. Neither child span explains the final 100 ms.
In this example, the two children cover 200 ms of elapsed time, and neither child accounts for the final 100 ms. The parent might be doing local work, waiting or calling something you have not instrumented. Start with what the recorded operations can tell you. Adding the two bar lengths will send you looking for time the request never spent.
Suppose a database span takes up most of a slow request. One responder suspects a migration is blocking queries; another wants to add capacity. Find the matching query and check what it was waiting on. A lock wait tied to a blocking session supports the first explanation. Sustained resource saturation without evidence of that blocker points to a different check. A later snapshot might miss the original wait, and neither observation by itself proves which change caused the incident. The trace earns its keep by narrowing the question to the query and the wait.
Compare the slow request with similar work
Pull up a faster request from the same release and region, with the same request type and dependency route where possible. A small request from another region may be fast for reasons that tell you little about this one. Look for the interval that changed while the surrounding work stayed comparable.
Check retries even if the request eventually succeeded. If attempts and backoff were recorded, you can see how much time passed before success and ask whether repeated attempts added load to the dependency. The final status alone cannot show that sequence.
Check what the trace set can tell you
Suppose a collector that favors errors retains 80 failed requests and 20 successful ones. Failures account for 80% of those retained traces. To estimate the service’s failure rate, use request metrics that cover the eligible population. The measurement completeness lab shows why you need to know what the denominator covers.
Inside one trace, clock differences between hosts can make the bars look out of order. Failed context propagation and lost telemetry can also leave a partial tree. Check those paths when a relationship or duration looks implausible. The instrumentation guide covers how to record a missing handoff.
Go back to the gap you started with. If it leads to a database call, check the query’s wait state. If the connection between two services is missing, check propagation at that handoff. You can make progress with a partial trace when the next check follows a relationship you actually observed.
Sources & context
Sources linked in this article. Read alongside the author’s analysis; a citation does not independently verify a publisher’s claims.
- OpenTelemetry overviewopentelemetry.io