
On this page4 sections
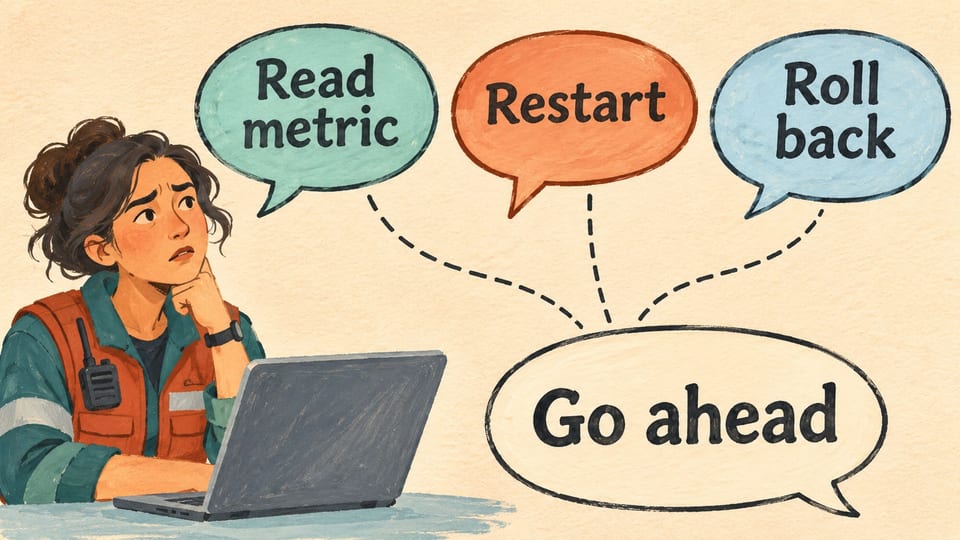
In a hypothetical incident channel, someone writes “go ahead.” Just above it are three suggestions: read a metric, restart a database and roll back an application. The people who have been talking may know which suggestion the reply belongs to. A bot arriving at the same words needs something more definite before changing production.
Slack is useful precisely because people can work through an incident together, without making every sentence a formal instruction. Keep that freedom in the conversation. When a decision has consequences, connect it to an identified proposal, its target and the result recorded by the system doing the work. Then a responder joining late can follow what was decided instead of guessing from the tone of the replies.
Help the next person catch up with the decision
The opening message gives a joining responder their bearings: the incident, affected service, current impact, coordinator and next update time. Links to the incident record, dashboards and maintained runbook give them somewhere to check the details. A stable channel-naming convention helps people find the conversation, without putting sensitive customer information in the name.
For our hypothetical channel, an illustrative update could read: “Database errors are affecting checkout. Priya is coordinating. The next update is at 14:30. The team is checking whether the latest deployment changed connection behavior; no rollback is approved yet.” The name and time are invented for this example. The update tells the newcomer what users are experiencing, who is coordinating, what the team is investigating and which decision has not been made.
Now suppose Priya approves the read-only check. The approval points to that check’s action identifier and target. The database restart has a different identifier and remains unapproved. Once the check finishes, a link to its result comes back to the channel. Someone can trace the question, the specific permission and what was found without turning “go ahead” into permission to restart the database.
Give other proposals the same clarity where it matters: show the action, target, required approval and planned outcome check, then post the result separately after execution. A suggestion can otherwise begin to look like a completed change as the conversation scrolls past it. Retain the timeline and relevant evidence in the incident record, and archive channels through the agreed retention process. Archiving the conversation alone does not guarantee that everything needed to reconstruct an action has been preserved.
Keep a second delivery from becoming a second action
The Slack Events API, which delivers Slack activity to applications, is a best-effort system and may retry events. Suppose our bot receives the same approved request twice. The second copy says nothing new about what the user wants done. The bot needs to recognize the event and find the action already recorded, rather than treat another delivery as another approval.
Delivery can also be late. By the time an old request reaches the bot, the incident may have moved beyond the conditions under which it was approved. If a database restart is later proposed, the approval must identify both that restart and the specific database. The execution system still needs to check the user’s authority and whether the current state permits the action. Being in the incident channel is not the same as having permission to restart its database.
Validate incoming requests and restrict the bot’s credentials to the access it needs. Keep read-only evidence retrieval separate from writes. A restart may take only a short instruction to invoke, yet interrupt active work or erase useful diagnostic state. The incident assistant design explores the durable records and partial-failure handling needed when several tools participate.

Read diagram description
The diagram follows four linked steps: Slack discussion holds the proposed action and supporting records; authorized execution names the specific resource and approved change; the destination record shows what was actually attempted or changed; and a service check verifies the outcome before it is reported to the channel. The drawing describes the proposed workflow, not a recorded execution or demonstrated recovery.
This precision has a cost in attention and recordkeeping, so apply it where it changes the decision. Low-risk coordination does not need a transaction record for every message. Actions that change system state, ownership or the declared status of the incident do need an explicit trail. People can keep discussing the problem naturally while those consequential steps remain identifiable.
Leave the unfinished part in the summary
A generated summary can save the next responder a long scroll. It should separate observed impact from possible causes, completed actions from open work, and link consequential claims to their messages or records. The newcomer can then inspect the part that affects their next decision instead of accepting the summary as the only account.
Consider what happens if “restart requested” becomes “database restarted” in that shorter account. In our hypothetical case, the tool could have timed out without returning a result. The cleaner sentence has removed the uncertainty the next shift most needs. They should inspect the destination before another attempt, rather than assume either that the repair completed or that nothing happened. Preserve the unresolved result in the summary until the record supports a more definite statement.
The summary also has an audience. Limit which material the assistant can read and where it can post; private channels and external connectors can change who receives the underlying data. Employee conversation is not a shortcut for judging someone’s performance or wellbeing. Helping a responder catch up does not require repurposing their conversation into those assessments.
Bring the bot back into the work people continued
Where reliability requirements call for it, paging and critical escalation need to work independently of Slack. Put the alternative bridge or communication method somewhere responders can discover outside the failed system. The route to runbooks and incident records must also remain reachable without first opening the missing channel link.
Before adding another write action, rehearse more than the successful exchange. Include ambiguous approval, a bot outage, expired credentials, duplicate delivery and unavailable chat. Responders should be able to locate the exact request, distinguish an established result from an unknown one and continue manually through the alternative route. That rehearsal tests whether the conversation and action records remain useful when the convenient path disappears.
When the bot returns, compare its pending requests with what people have already done. If they completed the restart manually, the returning bot needs to report that outcome, not carry out the old request again. The channel can then show the same incident the responders actually handled: which action was authorized, what happened at the destination and what the service check found.
Sources & context
Sources linked in this article. Read alongside the author’s analysis; a citation does not independently verify a publisher’s claims.
- Slack Events APIdocs.slack.dev