
On this page3 sections
Two services send their morning counts. One handled 100 requests and recorded two errors. The other handled 900 and recorded nine. A report that averages their two error rates says 1.5%. The report is tidy, and it has quietly given the service with 100 requests as much say as the one with 900.
Count the requests instead. Eleven out of a thousand failed, so the combined rate is 1.1%. The Python program below gets there from a local JSON file. It can tell you whether the counts are usable. Finding out whether all the counts arrived is a different job, and it matters just as much when the report goes out.
Let each request count once
Use Python 3 and put two files in the same directory. The first, input.json, holds these illustrative counts. The rows cover distinct sets of requests from the same time window.
[
  {"requests": 100, "errors": 2},
  {"requests": 900, "errors": 9}
]
Save the following as aggregate.py. Python’s standard JSON module reads the file and prints the result, so there is nothing else to install.
import json
import sys

def aggregate(rows):
    if not isinstance(rows, list) or not rows:
        raise ValueError("Expected a nonempty array of count records")
    requests = errors = 0
    for row in rows:
        if not isinstance(row, dict):
            raise ValueError("Each record must be an object")
        n, e = row.get("requests"), row.get("errors")
        if type(n) is not int or type(e) is not int:
            raise ValueError("Counts must be integers")
        if n < 0 or e < 0 or e > n:
            raise ValueError("Require 0 <= errors <= requests")
        requests += n
        errors += e
    return {"requests": requests, "errors": errors,
            "error_fraction": errors / requests if requests else None}

def main():
    if len(sys.argv) != 2:
        print("Usage: python3 aggregate.py input.json", file=sys.stderr)
        return 2
    try:
        with open(sys.argv[1], encoding="utf-8") as stream:
            result = aggregate(json.load(stream))
    except (OSError, UnicodeError, ValueError) as exc:
        print(f"Aggregation failed: {exc}", file=sys.stderr)
        return 1
    print(json.dumps(result, allow_nan=False))
    return 0

if __name__ == "__main__":
    raise SystemExit(main())
Run this from the directory with both files:
python3 aggregate.py input.jsonThe program exits with status zero and prints:
{"requests": 1000, "errors": 11, "error_fraction": 0.011}The larger service supplied nine of every ten requests. Its 1% error rate ought to pull the combined result closer to 1% than to 2%. Summing the counts first does exactly that: 11 divided by 1,000 is 0.011, or 1.1%.

Read diagram description
Over the same window, service A has two errors among 100 requests, or 2%. Service B has nine errors among 900 requests, or 1%. Their request sets do not overlap. Add to 11 errors and 1,000 requests, then divide to get 0.011, or 1.1%. Averaging the two rates instead would give 1.5%.
The program expects a nonempty list of objects, each with integer counts. It rejects negative counts and a row that reports more errors than requests. The exact type check handles a small surprise: Python treats booleans as a subtype of integers, but a JSON true is not evidence of one request. The program refuses it instead of giving it a place in the total.
A row of zero requests and zero errors is valid. If every row is like that, there were no requests to divide by and the program prints error_fraction: null. A hundred requests with no errors instead yields 0.0. One result leaves the rate unanswered; the other says what happened to a hundred requests.
A missing file, malformed JSON or invalid count sends an explanation to standard error and exits with status 1. It prints no partial result. Leave off the filename and it prints usage and exits with status 2. See the Python logging and exit status guide for how a scheduled job can keep those diagnostics away from its result stream.
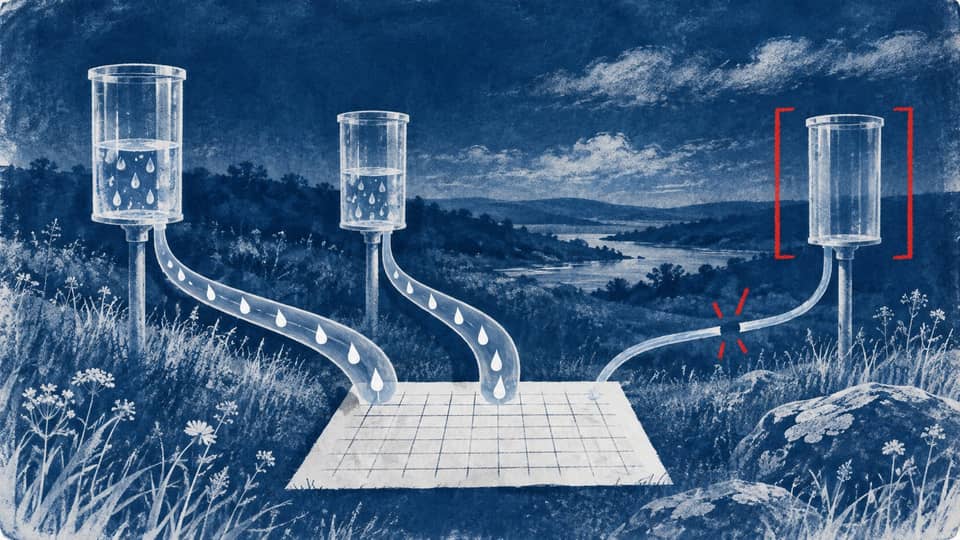
What if the third region never sent its rows?
Suppose east and west sent those two rows and central never replied. The program still prints 1.1%, and for the requests it received, that is correct. Give the same result a fleet label and it makes a claim the input cannot support. Central might be where most of the errors are.
Keep a record of which sources and pages you expected, what arrived, and which time window they cover. A source might reply successfully with no observations, reply with only some pages, or never respond. Record each of those conditions where you collect the data. This script rejects an empty list, so an entirely empty but successful collection needs its own outcome. With central missing, you can hold the fleet report or label the number “east and west only; central unavailable.” The narrower number can still answer a narrower question.
Keep the collector’s knowledge beside the total
When you add a client to fetch the counts, handle authentication, connect and read timeouts, response size limits and pagination. Check the response status and shape before handing anything to the aggregator. Give retries a limit and a delay that grows between attempts. If central’s third page still cannot be read, carry that failure and the freshness of the pages you have into the report. There should be a way to tell a complete morning from a partially received one.
The file format holds counts, so the script cannot tell whether two rows include the same requests or come from different time windows. Settle those questions before you add the rows. The metrics guide explains what happens to a rate when the underlying population changes.
When you try the program, keep the two sample rows and then try leaving an expected source out of the collection. The arithmetic should still say 1.1% for the requests in the file. The collection record should make it impossible to mistake those requests for the whole fleet.
Source context
Source links appear within this article. Read them alongside the author’s analysis and evaluate the guidance against your environment.
Report an error or outdated detail