
On this page4 sections
Imagine choosing storage for a team that runs AI jobs. The model files load promptly, the graphics processors start their calculations, and nobody spends the morning waiting for the job to begin. That is a useful result to have.
Now give the same hypothetical team a different task: resume a job after its original machines become unavailable. The job has saved its progress in a checkpoint, a file or set of files the application can use to continue. The replacement machines need to reach that saved state, read it correctly and put it back to work. Fast loading on the original machines has answered only part of their question.
NetApp and NVIDIA reference documents help you understand a tested storage configuration. To decide whether it fits your service, connect that configuration to both starting work and bringing interrupted work back. This guide follows those two paths; it is not a deployment walkthrough of either reference design.
The configuration behind the result
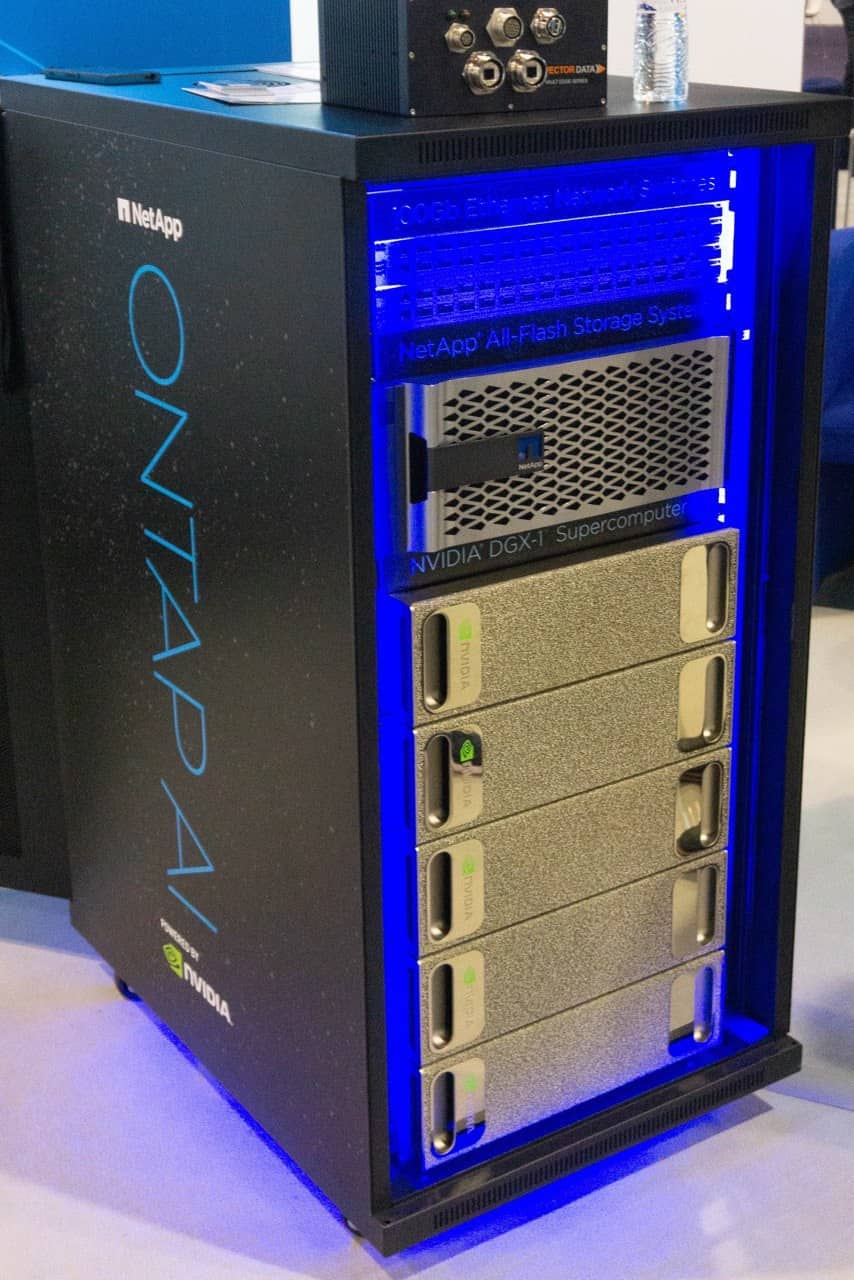
NetApp's ONTAP AI design for NVIDIA DGX A100 describes servers, storage, networking, firmware and software as a tested combination. The familiar product name is only the beginning of that description. Replace a component with a later member of its family and compatibility or performance may change with it.
The later NVIDIA-Certified Storage document supplies certification context. Keep the support guidance for the exact components you propose beside these documents. A performance test tells you what was evaluated; a recovery commitment in a contract tells you what a supplier has agreed to provide. You need to know which of those questions a document answers.
There is value in using work the suppliers have already done. Repeating every test would consume time without necessarily teaching your team anything about its own recovery path. Use the supplied results where the configuration and workload assumptions fit. Spend independent effort on the differences that matter, especially the conditions under which the team expects to recover.
Keep the conclusion about storage equally specific. Infrastructure that supports AI work does not, by itself, demonstrate automated fault diagnosis, remediation or a particular reduction in downtime. The useful question here is whether the proposed system can supply the data this job needs, in the circumstances where it needs it.
What does the job ask storage to do?
Picture the job opening a few large model files. Now picture it opening many small files, or regularly writing checkpoints as it progresses. Those requests put different demands on storage. File sizes, the number of simultaneous operations, checkpoint frequency and growth all matter. So does metadata work: finding and opening files involves more than moving their contents.
A large-file transfer result may therefore say little about a job waiting on many small operations. A repeated run can also benefit from data already held in a cache, ready for reuse. The first start after moving work away from failed infrastructure may not have that advantage. Both results can be accurate while describing rather different mornings for the team.
Measure useful work completed alongside time spent waiting for input, storage response times and whether the network is reaching its capacity. Keep the model, batch size and cache policy steady, or record what changed. Otherwise a busier graphics processor might reflect a different job or a warmer cache rather than the storage improvement you meant to assess. Include startup and restoration in the comparison so the measurements describe work you actually plan to perform.
The checkpoint is there. Can the replacement reach it?
Return to our hypothetical job. Its checkpoint sits behind a private storage endpoint, an address through which the application accesses the store. The original group of machines can reach it. The alternate group starts successfully, but has no permitted network route to that address. Everything needed to run the calculations is waiting for the first byte.
That is a useful place to begin a controlled recovery exercise. From the alternate machines, can the application resolve the endpoint's name, connect and retrieve the named checkpoint? If it cannot, investigate that access path before treating the checkpoint as damaged. More compute capacity cannot provide a route that is missing.
When the bytes arrive, the next question becomes possible: are these the right, intact contents, and can this application use them? A checksum, a value calculated from the data, can help check integrity against an expected value. Application-level validation checks what the application needs from the saved state. Receiving a file alone does not establish compatibility with its format or that the job can resume.
Keep watching until the application continues useful work, and measure how long that takes. A snapshot can preserve data without establishing this final step. The route, the saved contents and the application's continuation each explain a different way recovery might stop or take too long.
Plan the exercise with the people responsible for the dependencies involved. A broken connection, an interrupted checkpoint write, limited capacity and an unavailable management service pose different problems. Establish where the recovery is automatic and where someone must decide how to continue. This is proposed testing, not a report of tests performed on either vendor design.

Trace the shared dependency
Both compute pools connect to one model and checkpoint store. The alternate is a different place to run the job, but it may still need the storage path affected by the failure. This is a conceptual dependency diagram, not a vendor test. Diagram labels: Model + checkpoint store: Recovery artifacts and their versions; Primary compute pool: Reads artifacts through storage path; Alternate compute pool: May need that same path to recover; Recovery question: Can the alternate pool start useful work if storage is unavailable?
The shared store also explains why the handoff between compute, network and storage teams matters. An alternate group that needs the same unavailable store can inherit the original problem. Give the team responsible for the blocked path the failing endpoint and the observations from the alternate location, so the next action addresses that path rather than simply starting more machines.
The findings now point to different work. A blocked connection calls for network or access investigation and any approved changes it requires. An unreadable checkpoint calls for artifact or application work. A job that resumes correctly but too slowly reveals a recovery-time limit. Installing the intended configuration can be complete while one of those service questions remains unresolved.
The system the team will keep running
Performance is part of what you buy and operate. Licensing, staffing, migration, backups and moving data are part of it too. Compare the candidate with current storage using the same workload and objective, with those costs visible. The team will still be paying them after the performance trial finishes.
The power and cooling guide follows another part of the same capacity problem. Compute, power, cooling and storage constrain the service together. Understanding one strong component means knowing what the others must supply and how they behave when something is unavailable.
For our team, the selection now includes two recognizable jobs: getting the model into a working system, and getting saved progress into the machines that must continue it. Keep the quick load in the comparison. Keep the alternate's route to the checkpoint there too. They are both things the people waiting for the job will eventually need.
Sources & context
Sources linked in this article. Read alongside the author’s analysis; a citation does not independently verify a publisher’s claims.
- ONTAP AI design guide for NVIDIA DGX A100 systemswww.netapp.com
- NVIDIA-Certified Storage design documentwww.netapp.com