
On this page4 sections
A language model can describe a service's health without having any way to inspect it. Tool calling connects the conversation to software: the model requests a named operation with arguments, the application decides whether to perform it, and the result returns to the model for the next response. That exchange is the useful starting point for understanding an AI agent.
An agent application can repeat this cycle while working toward a goal. The model helps interpret the situation and choose a next step; the surrounding software supplies tools, state and limits. The word “agent” does not establish what it can access or what it is allowed to do. Those are properties of the application you build or configure.
Follow one complete exchange
The OpenAI function-calling guide describes the tool-request, application-execution and returned-result cycle. Other providers expose similar ideas with different message formats. A tool schema tells the model which arguments an operation accepts; it does not itself execute the operation or replace the application's authorization checks.
Consider a hypothetical assistant answering “What is the catalog service's recorded health?” Give it one read-only function, get_service_status, restricted to two synthetic services. The following standard-library Python fixture exercises the application side. The model request is a recorded example, not a real model response or live infrastructure query.
import json

status = {"catalog": "healthy", "search": "degraded"}
call = {
    "id": "call-example-1",
    "name": "get_service_status",
    "arguments": '{"service":"catalog"}',
}

def execute(call):
    if call["name"] != "get_service_status":
        raise ValueError("unsupported tool")
    args = json.loads(call["arguments"])
    if not isinstance(args, dict) or set(args) != {"service"}:
        raise ValueError("unexpected arguments")
    service = args["service"]
    if not isinstance(service, str) or service not in status:
        raise ValueError("service outside allowed scope")
    return {"service": service, "status": status[service],
            "provenance": "synthetic fixture"}

result = execute(call)
reply = {"call_id": call["id"], "output": json.dumps(result)}
print(json.dumps(reply, indent=2))
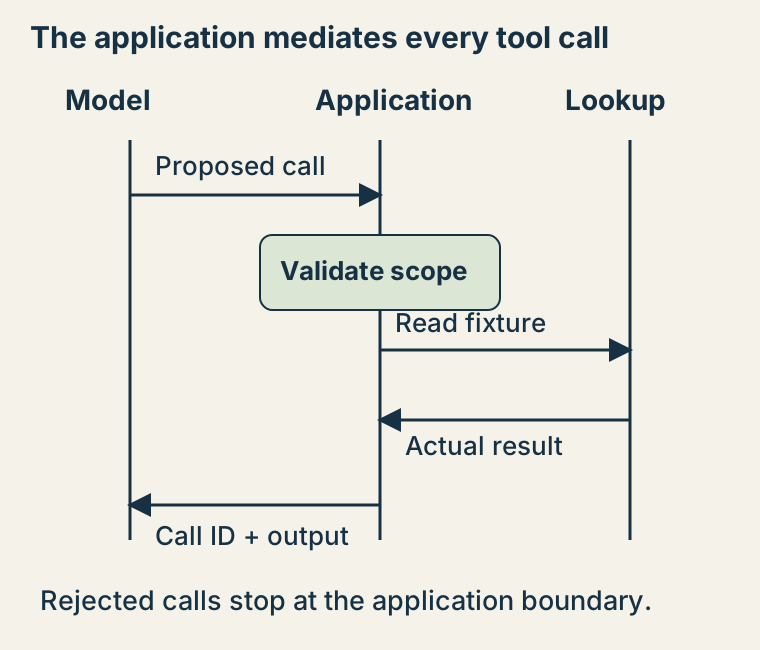
The application checks the function name, argument shape and allowed service before reading the fixture. The returned call ID connects the result to the request. In a real API integration, place that output into the provider's documented tool-result format and send it back for the model's continuation. The plain dictionary here is intentionally provider-neutral, not a message you can submit unchanged to every API.
The useful continuation would say that the fixture records catalog as healthy, while preserving its synthetic provenance. It should not claim to have checked the real service. Replacing the fixture with a real status API requires a trustworthy observation time, error handling and the permission to read that service.
A proposed call is not authority
Try changing the fixture's function name to restart_service, adding a force argument or naming an unlisted service. Each should be rejected before the operation runs. Those failures demonstrate the application's boundary. Asking the model to “only use safe tools” is useful guidance, but it is not a substitute for enforcing the boundary in software.
Keep a deterministic operation deterministic. Reading the status dictionary does not need a model to invent a result. The model may interpret the user's wording or explain the returned evidence; the application should perform the lookup and retain its result. This separation makes a mistaken interpretation distinguishable from a failed or unauthorized operation.
What changes when a tool can write
A read-only lookup is a suitable first exercise because it teaches the exchange without modifying a service. A write adds another question: was this bounded action approved against the state that still exists now? A request to improve health is not automatically permission to restart every component that looks relevant.
Writes also need recovery behavior. A timeout may mean the destination applied an operation but the reply was lost. Repeating it blindly can duplicate work. The write-reconciliation guide explains how to retain an unknown outcome and inspect the destination before retrying. Some actions, such as sending an external notification, have consequences that cannot simply be rolled back.
When a loop is useful
Use an agent loop where a task benefits from interpreting intermediate evidence and choosing among bounded next steps. If a stable rule already determines the next operation, ordinary automation is usually easier to inspect. The distinction is about the work, not whether a model can be inserted into the path.
Before expanding the example, test invalid arguments, unavailable results and a task the allowed tools cannot complete. Set a limit on iterations and cost, and retain the actual calls and outputs needed to understand a result. A useful assistant can report that it lacks a necessary tool. It does not need broader access merely to make the conversation end with a success claim.
Sources & context
Sources linked in this article. Read alongside the author’s analysis; a citation does not independently verify a publisher’s claims.
- OpenAI function-calling guidedevelopers.openai.com