
On this page3 sections
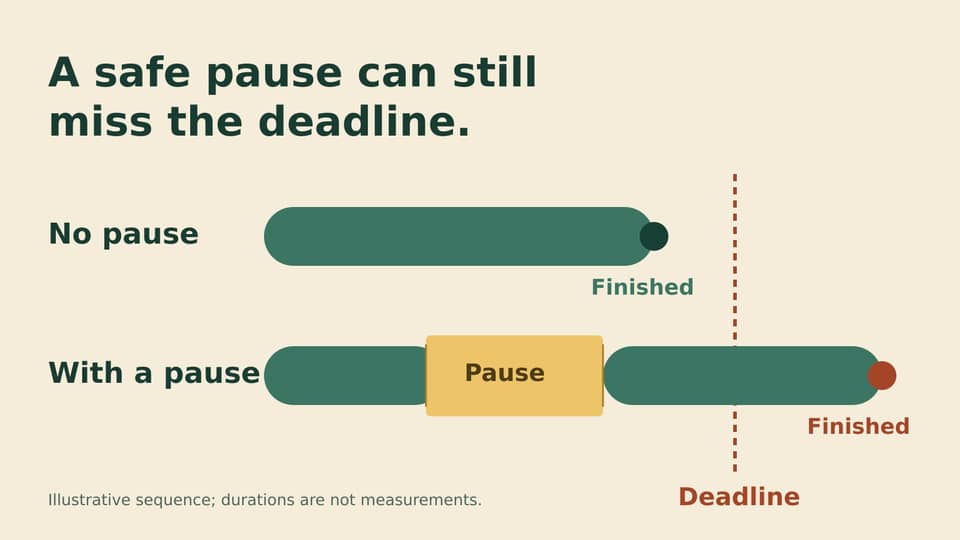
A team is waiting for an evaluation result before deciding whether to release a model. The job can pause without losing its work. That sounds reassuring until a request to reduce electricity use arrives in its final hour. In this hypothetical case, the job can survive the pause and still finish too late to help anyone make the decision.
That distinction matters to the AI Energy Management Alliance announced by NVIDIA, Emerald AI and Google on September 16, 2026. The industry initiative backs data centers that can adjust their demand on the electricity grid, with measurable response speed, duration and predictable emergency behavior. It is not a new job scheduler or a guarantee of faster permission to connect. For the team waiting on that evaluation, flexibility means deciding which work can move, and how far.
The battery and the scheduler have different jobs
Pausing the job is not the only way to help. The alliance describes storage, generation located alongside the facility, and software-controlled AI workloads as ways to change demand. A battery or generator may reduce electricity drawn from the grid while the evaluation keeps running. Conversely, stopping one job does not by itself establish how much less power the whole facility will draw.
So the facility operator and the workload owner have a conversation before the scheduler gets an instruction. What reduction is being offered? How will it be measured? Which jobs may move, and who can authorize the resulting delay? The scheduler can carry out their answer. It cannot decide that a release deadline no longer matters because nobody discussed it.
For our evaluation, a request in the final hour leaves a real choice: move the decision deadline, supply the reduction another way, or decline that reduction. Calling the job “interruptible” tells us it can stop safely. It does not choose among those outcomes. Storage and generation need the facility operator's participation; they are not controls the application scheduler can simply reach for.

The busy part may begin when the pause ends
When the power request ends, the waiting jobs may all want their turn back. They compete for computing capacity, storage and network access. Letting them restart together can crowd neighboring work; spreading their return protects those neighbors but makes some results later. The electricity meter may be back to normal just as the busiest part of the workload recovery begins.
Follow the evaluation through that return. Can it resume from a verified checkpoint, a saved position in its work, or must it repeat steps or start over? When does a valid result become available, and what happens to the jobs beside it? These are proposed checks for the team's rehearsal, not measurements reported by alliance members.
The answer also depends on what the service promised. Service-level objectives put that promise in measurable terms. For an interactive model, it may be successful replies within a specified time. For this evaluation, the result has to arrive before the release decision. Average utilization, how busy the equipment was, does not tell us whether either promise held.
Agree on the return, not just the reduction
NVIDIA says power-reduction and emergency-response commitments should be defined before a facility connects, alongside technical requirements and operational data sharing. For the people running our evaluation, that agreement needs to cover the return as well as the pause: the reduction, the response window, the decision owners, the recovery limit and the service measurements that would stop the test.
There is room to choose, but not to hide the cost of a choice. Slower restarts may protect other services while pushing the evaluation past its deadline. Storage or generation may leave the evaluation alone, but the facility operator must arrange and control that response. The workload owner needs to agree to the interruption and restoration that their service can actually tolerate.
A rehearsal answers only for the load and failures it exercised. A heavier workload or a second failure at the same time can change the return to normal. Test those conditions before extending the commitment; a successful pause on one occasion does not make every future pause safe for the deadline.
Bring the evaluation's deadline and its measured time to resume to the power discussion. If the result would arrive too late, choose another way to reduce demand or explicitly move the decision. The job's ability to wait is useful. So is knowing who is still waiting for the job.
Sources & context
Sources linked in this article. Read alongside the author’s analysis; a citation does not independently verify a publisher’s claims.
- NVIDIA: AI Energy Management Allianceblogs.nvidia.com
NVIDIA’s announcement: alliance participants and the proposed approach to flexible AI infrastructure.
- AI Energy Management Alliance: mission and approachwww.aema.ai
The alliance’s own overview of power flexibility. Describes its aims, rather than independently measured reliability outcomes.