
On this page4 sections
Imagine reviewing two charts before deciding whether to page. In the first, traffic rose during a weekend promotion, requests took longer and the queue grew, but customers could still finish. In the second, a familiar fault slowed some jobs past their deadline. A model trained on ordinary weekdays does a worse job recreating the promotion than it does recreating the fault. This is a hypothetical result, and it gives us a useful question. What did the model learn to recognize?
A variational autoencoder, or VAE, learns to represent a window of measurements in a small set of internal variables. From that representation it tries to recreate the input. You can score the difference between the original and its reconstruction, but before you put that score on a pager, follow the measurements through the model.
How a window becomes a range of possible codes
Start with the promotion window: request rate, latency and queue depth measured over the same stretch of time. An ordinary autoencoder turns that input into one internal code. A common VAE uses its encoder to describe a distribution of possible codes, then passes a sample to the decoder. The variables in the code are called latent because the model infers them from the measurements. They come with no labels for promotions or faults.
In the Gaussian example, the encoder calculates a mean μ and a standard deviation σ for each coordinate. Draw noise ε from a standard normal distribution and compute z = μ + σ × ε, multiplying coordinate by coordinate. The noise stays independent of the encoder's output, while the result changes smoothly with μ and σ. That lets training compute how adjusting the encoder would change the sampled code and its reconstruction. Kingma and Welling explain this reparameterization in Auto-Encoding Variational Bayes.
The encoder's distribution is called the approximate posterior because it estimates which latent codes are plausible given the input. During training, the decoder learns to assign probability to the observed window given a sampled code. The objective, called the evidence lower bound or ELBO, balances that fit against a penalty for moving the encoder's distribution too far from a chosen reference distribution, the prior. A code for each training example might make those examples easy to recreate, but the penalty gives the model a reason to arrange the codes in a space it can sample from.
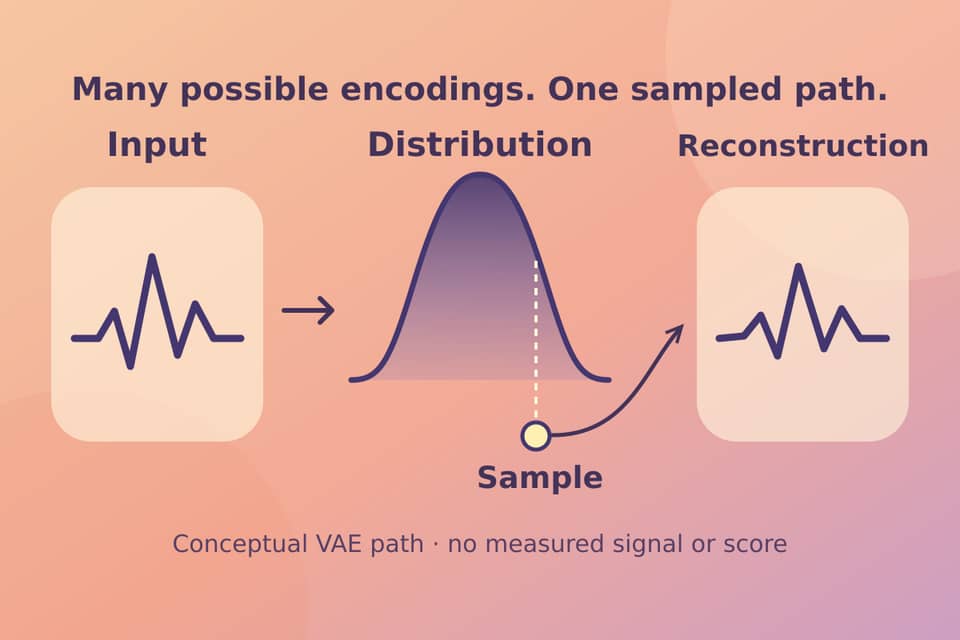
After training, the two uses start in different places. To reconstruct a particular window, encode it and draw from the resulting distribution. To generate a window without a particular input, draw from the prior and use the decoder. The drawing below follows the reconstruction path.

Read diagram description
A preprocessed telemetry window x enters the encoder, which gives the approximate posterior parameters μ and σ. Sample standard normal noise ε to compute z = μ + σ × ε. The decoder uses z to model the input x. Training balances the fit to the input with regularization toward the prior.
The model needs a consistent view of the measurements
Suppose the training pipeline recorded latency in seconds and today's input reports milliseconds. The same wait has a number a thousand times larger. If the scale changes, reconstruction error can rise while the service behaves as before. Align the units and fit scaling on the training period. Treat gaps, counter resets and changes in collection interval consistently, so a measurement problem does not become a service diagnosis.
The model can learn that a combination of request rate and queue depth is familiar without knowing why. More structure can help when it gives the model relevant information. A conditional VAE can use a known workload label alongside the measurements. A hierarchical VAE uses several levels of latent variables. A decoder need not mirror the encoder, and Gaussian codes are one modeling choice. Try a different design only when you can check what it improves on your data. A label for the promotion is useful context if you also have it when scoring future windows.
The fault may be easy to reconstruct
The hypothetical promotion is unfamiliar to the weekday model. The fault may occur often enough for the model to recreate it. A release can do something similar to the promotion by changing resource use without hurting the customer. The score describes what the model can recreate. Use a separate check of whether the customer can complete the operation or whether jobs still meet their deadline.
Also check that the decoder is using the code. In posterior collapse, the encoder's distributions can approach the prior and the decoder can learn to ignore information about the individual input. Average training loss alone won't tell you how useful that representation is. Inspect what happens when the decoder receives codes from different windows and compare it with what happens when you draw from the prior.
Find out what the score would ask someone to do
Set aside later data for evaluation before you fit the model or its scaling. Use a validation period to choose the threshold and a separate test period to assess it. Check for overlapping windows and incidents that cross a split. If nearly the same measurements appear on both sides, the test can reward familiarity with the training set.
Keep the input window and relevant features beside the score so an engineer can see what changed. On the later data, compare the VAE with a simple threshold or a seasonal baseline. Count which incidents each missed, which flags sent someone to investigate a healthy service and whether the useful signal came in time to act. Lowering the score threshold might catch more faults while making the promotion one of many unnecessary calls. Raising it might quiet the pager while missing more.
The anomaly detection guide shows how to compare those outcomes, and the GAN explainer examines a different way to generate samples. In our example, the promotion might warrant a look during staffed hours. The recurring fault still needs its own service check if the VAE misses it. Before letting the new score wake someone, show which decision it improves and keep the independent signal for failures it cannot see.
Sources & context
Sources linked in this article. Read alongside the author’s analysis; a citation does not independently verify a publisher’s claims.
- Auto-Encoding Variational Bayesarxiv.org