
On this page5 sections
A rollback is proposed, support needs an update and three responders are checking the workers. Before anyone changes production, someone needs to decide which work comes first, who will carry it out and who can authorize it. Being busy does not settle any of those questions.
This tabletop continues the fictional Dispatch incident from lesson 1. Two exports from different accounts are verified late, the API health check succeeds and a worker deployment preceded the reports. The cause and full scope remain unknown. You will organize that response using an illustrative training policy and named responsibilities; no production access or external communication is needed.
Severity connects impact to a response
The first lesson established why these verified delays warrant coordination. Severity makes the expected response more specific: who needs to join, how urgent the work is and which escalation route applies. A numbered label only has meaning alongside the organization’s policy, so this exercise uses three local training levels:
| Training level | Condition | Response expected |
|---|---|---|
| Investigate | One unverified report, with scope unknown. | An on-call responder checks the reported operation and records what they find. |
| Coordinate | Multiple independently verified exports miss their completion deadline. | Name a response lead, keep one shared record and involve the service owners needed for the investigation. |
| Expand | Evidence establishes broad loss of a critical operation, or a condition needing specialist escalation. | Add the technical specialists and decision makers required by that impact. |
Dispatch meets the Coordinate condition because two exports are verified late. The successful health check does not undo that result: it checks the API process, while the failed user operation includes background processing. There is enough evidence to organize the response without claiming that every export is affected.
If later evidence shows an export reached the wrong user, the response needs the organization’s security or privacy escalation path even if only one affected export is known. The nature of the harm can matter more than its count. Keep the impact statement current so that severity follows what responders actually know.
Give three responsibilities someone’s attention
The response needs coordination, technical execution and communication. Google’s incident-management guidance separates these responsibilities so that a technical investigation does not leave the rest of the response unattended.
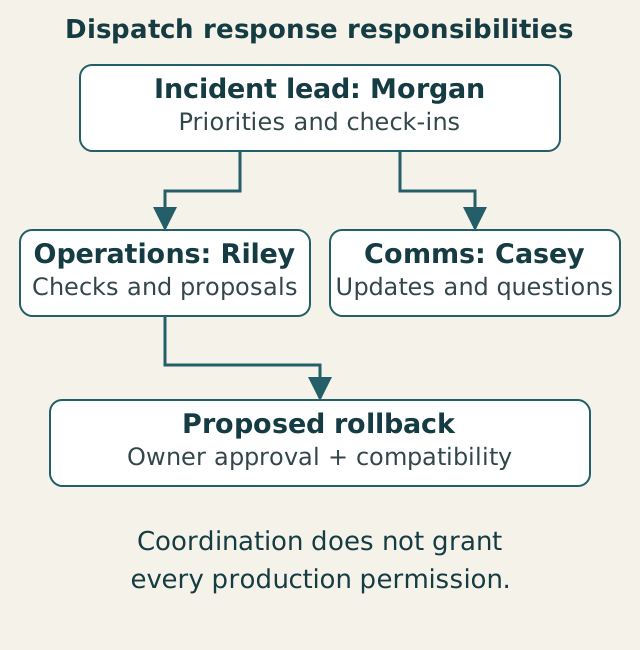
For Dispatch, Morgan accepts the incident-lead role, Riley takes operations and Casey takes communications. Morgan keeps the next priorities and check-in clear. Riley directs the technical investigation and proposed mitigations. Casey prepares updates from the shared facts and brings support’s questions back to the responders.
Make the assignment a short exchange. Morgan asks, “Riley, can you check whether the affected jobs are waiting or making progress, and report back at 14:15?” Riley accepts. The task now has a person doing it, a result to bring back and a time to revisit it. Simply putting Riley’s name in a document would not establish that they had seen the request or could take it.
With two responders, Morgan could combine incident leadership and communications while Riley handles operations. If updates keep interrupting Morgan’s coordination, request someone to take communications and explicitly hand it over. Roles help divide attention; an empty box on an organization chart does not do the work.
Who can authorize the rollback?
Riley proposes reverting the worker deployment because it happened before the delays. That is a hypothesis worth checking, but timing alone does not establish cause. The proposed action also has a separate requirement: this exercise’s change policy needs service-owner approval and confirmation that the old worker can read data written by the new version.
Incident command coordinates the response; it does not automatically confer authority to make every production change or accept every risk. Riley’s ability to deploy does not answer the compatibility question, and Morgan’s incident-lead role does not replace the required service-owner approval.
Morgan can move the response forward by asking Riley to establish data compatibility and bringing the service owner into the decision. Record who owns the compatibility check, who can approve the rollback and what evidence will show whether it helped. Here, the outcome check should follow affected exports through processing and verify that new exports complete within the expected deadline. Another green API health check would not demonstrate that improvement.
Some familiar mitigations may already be delegated through a reviewed runbook. Use that existing authority where it applies; the lesson is not to create an approval queue for every routine step. The rollback in this scenario needs explicit attention because its stated compatibility and approval requirements are still unresolved.
Make the current state easy to join
A new responder should be able to join without asking the whole room to reconstruct the last ten minutes. A concise working record can provide that starting point:
Dispatch exports delayed | Investigating
Known impact: two verified late exports in two accounts
Full scope and cause: unknown
Training level: Coordinate

Morgan: incident lead, accepted
Riley: operations, accepted
Casey: communications, accepted

Riley: locate the wait for the affected jobs; report at 14:15 UTC
Riley: establish whether the previous worker can read current data
Service-owner approval: requested; awaiting acceptance
Proposed rollback: pending compatibility check and approval

Success check: affected jobs progress; new exports meet deadline
Next update: 14:15 UTC
The distinction between “accepted” and “requested” matters here. The first three responders have taken their roles, while the service-owner request is still outstanding. Morgan must follow that request rather than assume the missing approval is being handled.
Reassess when the facts change
Run the exercise with only two people available. Assign technical, coordination and communication work, then write the request for additional help. Consider two new observations separately: a third verified late export appears in another account; an export is confirmed exposed to the wrong user. Decide what each changes in the response.
Compare with a worked response
Morgan accepts incident leadership and communications; Riley accepts operations. Morgan requests a communications responder so updates do not block coordination. A third verified delay adds an account to the impact statement and makes checking scope more urgent, but it does not alone establish broad loss of the service’s critical operation. Confirmed wrong-user exposure triggers the relevant security or privacy escalation path immediately. Neither observation authorizes the pending rollback: Riley’s compatibility result and the required service-owner decision still need to be resolved, or another mitigation selected through the applicable process.
The response is now organized enough to act deliberately. Someone is checking the delayed work, someone is maintaining priorities and updates, and the rollback has a clear route to a decision. The next lesson builds on that record by separating event times, observations and hypotheses as the investigation develops.
Sources & context
Sources linked in this article. Read alongside the author’s analysis; a citation does not independently verify a publisher’s claims.
- incident-management guidancesre.google