

On this page6 sections
You do not need a finished explanation of a failure before organizing a response to its effects. If users cannot complete important work, waiting for a root cause can leave several people investigating independently while nobody maintains a shared view of the impact.
Starting an incident response gives that work a common place, a coordinating lead and a record others can join. It does not certify a diagnosis or make every proposed mitigation safe. The first useful result is simpler: responders agree on what is known, what needs checking and who is handling the next step.
This lesson is a tabletop exercise. You will work from a small packet about Dispatch, a fictional report-export service, and draft the opening incident record and update. You will not page anyone, send a customer message or change a running system.
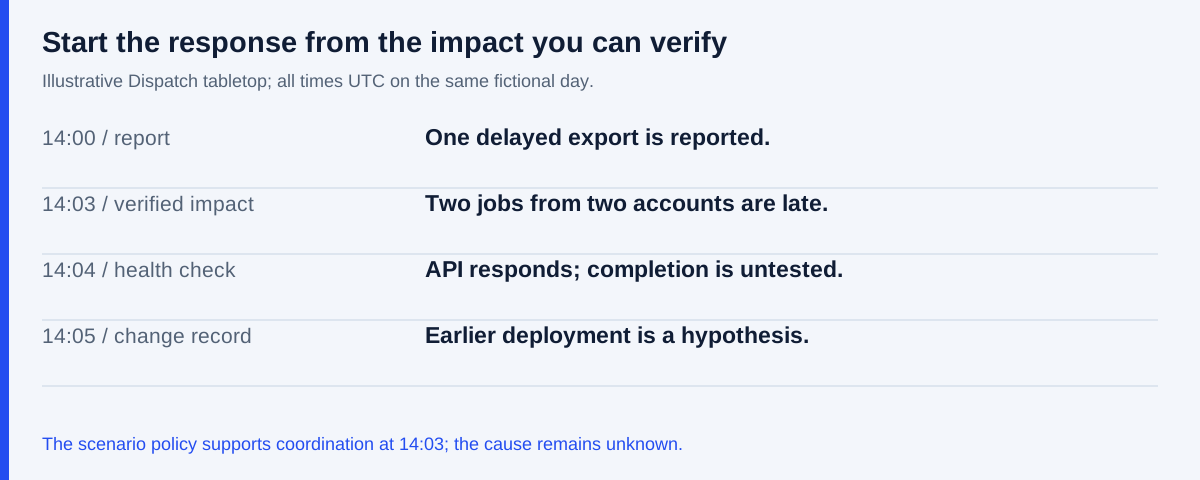
Look for the interrupted user operation
Dispatch accepts report requests, creates files in a background worker and makes them available for download. Returning a job identifier means the request was accepted. It does not mean the report has been generated.
At the start of the exercise, responders have the following information. All times are UTC on the same fictional day; they are supplied scenario facts, not captured production events.
| Time | Observation | Limit of the observation |
|---|---|---|
| 14:00 | Support records a user report: an export accepted at 13:40 is still pending. | One reported failure does not establish the affected population. |
| 14:03 | A responder checks that job and a second job from another account. Both remain pending beyond the product’s stated completion deadline. | Two verified delayed jobs establish impact to those jobs, not the whole service. |
| 14:04 | The API health endpoint responds successfully. | This endpoint checks the API process, not worker completion. |
| 14:05 | The change record shows a worker deployment at 13:35. | The deployment preceded these observations; timing alone does not establish cause. |
This packet supports a concrete initial impact statement: at least two accepted exports are delayed beyond the expected completion deadline, affecting two accounts. The full scope and impact-onset time remain unknown. The successful health check does not contradict the delays because it measures a different part of the service.
A report time and an onset time are also different. The first support report arrived at 14:00. The supplied record does not establish exactly when the service began failing, and it does not show whether earlier exports were affected. Preserve that uncertainty instead of turning the first message into a precise outage start.
Use the response policy before inventing a severity
In this training scenario, the response policy says that multiple independently verified exports missing the product’s completion deadline warrant a coordinated service response. That rule is supplied for the exercise. In a real organization, use its incident declaration and escalation criteria, including any safety, security or regulatory route that applies.
Under the exercise rule, the responder has enough evidence to start coordination at 14:03. There is no need to wait for the 14:05 deployment observation or a proven cause. The reason to declare is the verified interruption to user work.
The packet does not provide a numbered severity matrix, so assigning “SEV1” would add an unsupported classification. Record the observed impact, use the local policy to determine severity and revisit that decision as scope becomes clearer. A security-sensitive failure or a high-consequence customer operation may require escalation even when the known request count is small.
If the organization has no clear route and material user impact is ongoing, contact the established on-call or escalation function and state the facts. Do not delay reporting while designing an incident process from scratch.
Give the response a shared starting point
For a small incident, the opening record can be brief. It should help the next responder understand the problem without reconstructing several chat conversations.
Incident: Dispatch exports delayed
Status: Investigating
Known impact: Two verified accepted exports remain pending beyond
             the expected deadline, affecting two accounts.
Scope: Full affected population and regions are not yet established.
Timing: First report received 14:00 UTC; impact onset is unknown.
Coordination lead: Assign and confirm acceptance.
Technical lead: Assign and confirm acceptance.
Next checks: Compare export completion before and after 13:35 UTC;
             inspect pending-job age and worker results.
Cause: Unknown. Worker deployment is a hypothesis to investigate.
Next update: 14:15 UTC in the incident record.
The 14:15 update is a scenario choice, not a universal communications interval. Pick a real cadence to suit impact and your response policy, then give the next update even if the diagnosis is still unresolved.
The lead fields are deliberately unassigned in the exercise record. Writing a person’s name does not establish that they have seen or accepted the responsibility. In a real response, confirm who is coordinating and make that visible to the participants. One person may initially coordinate and investigate, but should ask for help when those responsibilities compete.
Coordination also does not grant every production permission. The lead can organize a rollback proposal while the appropriate service owner checks compatibility and authorizes the action. The next lesson develops those responsibilities; for now, keep the proposed investigation distinct from permission to change the service.
Write an update that matches the evidence
At 14:06, draft the first internal update using only the packet. It should describe the user effect, current work and the next update, while leaving the cause unresolved.
A suitable worked example is:
We are investigating delayed report exports in Dispatch. Two accepted jobs from separate accounts remain pending beyond the expected completion deadline; the full scope is still being checked. The API health endpoint responds, but it does not check export completion. We are reviewing pending-job age, worker results and the deployment at 13:35 UTC. The cause is not established. The next update will be posted here by 14:15 UTC.
The message does not promise that reports will be available by 14:15. It promises another update. It also avoids saying that the worker deployment caused the incident or that every user is affected.
A customer-facing update may need different detail and must follow the organization’s communication policy. The internal draft is not authorization to send it externally. For this exercise, keep the message in the tabletop record.
Check the response you started
Read your opening record as if you were a responder joining at 14:10. Can you identify the verified impact, the unresolved scope, the person coordinating and the next check? If a lead has not accepted responsibility, the record should say so rather than imply that coordination is covered.
Now test two tempting statements against the packet. “The API is healthy, so there is no incident” overlooks the failed export operation. “The deployment caused the outage” converts a sequence of events into an explanation the evidence has not established. Rejecting those statements leaves a useful investigation: determine which work is delayed and test whether the deployment or another condition explains it.
Save the record and the 14:06 draft together. The next lesson assigns response roles and a shared working record so investigation, action and communications can proceed without competing for the same person’s attention.
Sources and example scope
Google’s incident-management guidance and incident-response workbook support early coordination, clear responsibilities and a shared record. The site’s mitigation-authority guide explains why coordination and production authorization remain distinct. The existing MTTD guide retains the distinction between onset and discovery. Dispatch, its response rule, timestamps and messages are constructed course material. No incident was declared and no message was sent while preparing the lesson.
Sources & context
Sources linked in this article. Read alongside the author’s analysis; a citation does not independently verify a publisher’s claims.
- Google’s incident-management guidancesre.google
- incident-response workbooksre.google