
On this page3 sections
Somewhere behind the empty screen, the model has already started answering. The reader sees none of it because a gateway is holding the response until it is complete. Streaming lets that first useful text through while generation continues. The wait has changed even if the model is doing exactly the same amount of work.
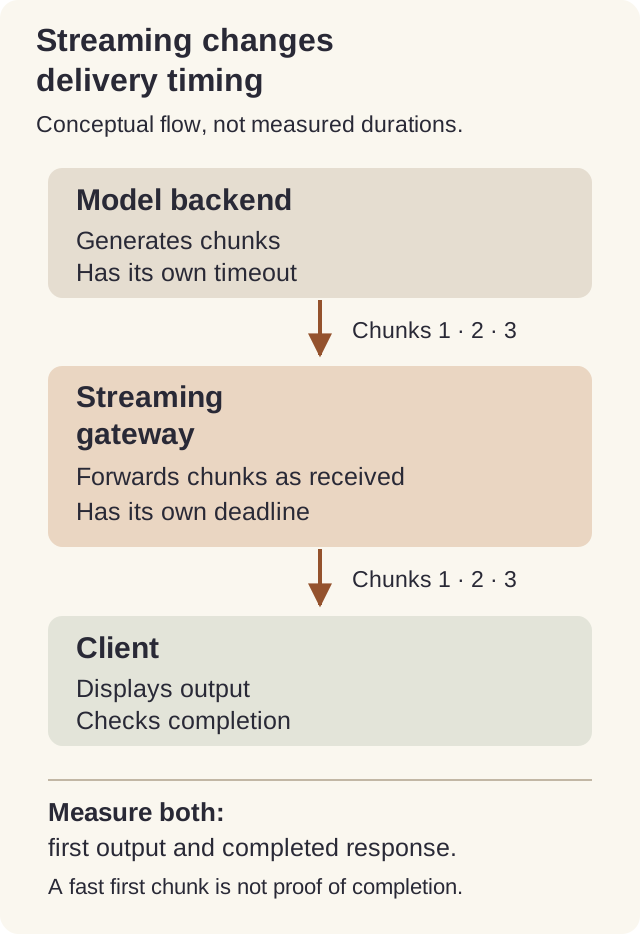
Google Cloud API Gateway introduced that option in the public preview listed in its September 29 release notes. It supports incremental HTTP delivery and Server-Sent Events, which send updates from server to client, as well as two-way streams through WebSockets and gRPC. For someone reading an explanation, earlier delivery can be a meaningful improvement. It does not make the model itself generate faster.
An existing endpoint needs a migration plan
The configuration guide specifies streaming at gateway creation, with --enable-streaming as the explicit flag. The output-only effectiveStreamingMode field reports the resolved mode. Once created, that mode cannot be changed. An established non-streaming gateway therefore needs a replacement or a traffic-migration plan, rather than an in-place switch.
There is also a deadline for the response to finish. HTTP streaming, including Server-Sent Events, defaults to 15 seconds; a streaming-enabled gateway supports a configured limit up to 3,600 seconds. That is a clock on the whole request. Another arriving chunk does not reset it.
The backend can have its own timeout, so extending only the gateway's limit may simply move the point where the answer stops. This remains a preview under pre-GA terms, before general availability, with potentially limited support. A separate trial endpoint gives you somewhere to examine those boundaries deliberately.
An opening sentence is not a completed answer
Imagine an incident assistant that takes 25 seconds to assemble an answer from service information. This is a hypothetical example, not a benchmark. Streaming could let the responder begin reading earlier. But if a shorter deadline closes the connection, the promising opening is all they get. The interface has become more responsive without finishing the requested work.
Compare buffered and streaming delivery with the same prompts, model settings and simultaneous demand. Put completed answers and interruptions beside the time to first useful output. Otherwise a faster-looking result may include requests that simply stopped before the difficult part, rather than the same work delivered sooner.
A slow backend and a departing reader reveal different behavior. In a trial, disconnect the client and inspect whether the interface clearly identifies the partial answer, and whether backend work continues after its reader has gone. These are proposed tests, not claims about outcomes observed on Google's service.
Who can use an unfinished response?
A person can often start reading the first paragraph while the next is arriving. A program waiting for a complete object may need the whole response before it can validate and use it. Streaming helps those clients differently. The choice depends on what the recipient can do with an early piece.
Keep the preview on a separate gateway with a route back. Our guide to reading distributed traces can help locate what changed: the time spent delivering text through the gateway, or the underlying work that produced it. Include gateway errors and incomplete application responses, not only the satisfying examples where the screen filled quickly.
The useful report has two observations: when something worth reading appeared, and whether the complete answer arrived. A reader can appreciate the earlier start without pretending the ending is optional. That is the improvement streaming should earn.
Sources & context
Sources linked in this article. Read alongside the author’s analysis; a citation does not independently verify a publisher’s claims.
- September 29 release notesdocs.cloud.google.com
- streaming configuration guidedocs.cloud.google.com