When recovery time needs a change to the plan
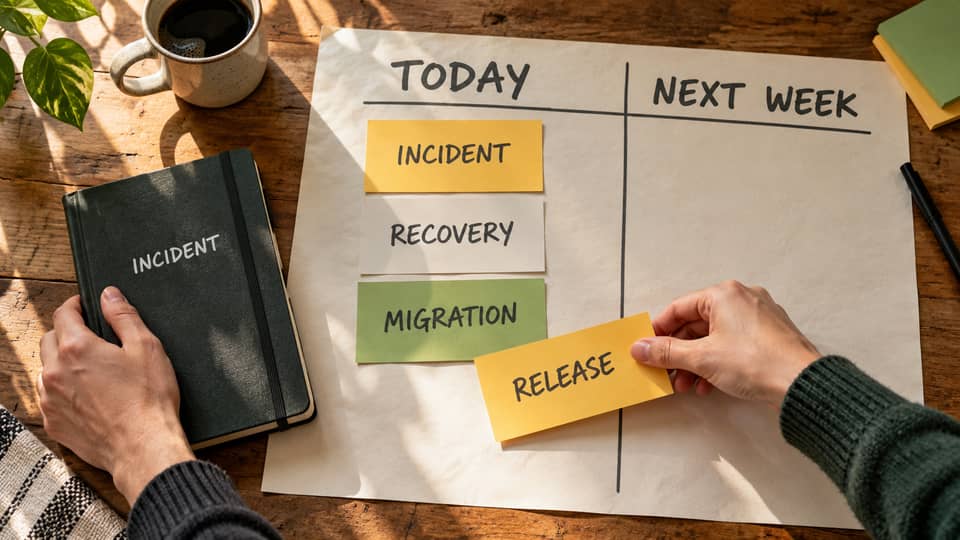
Relief after an interrupted night needs coverage and moved commitments. Then follow the recurring demand so the next week asks less of the same people.
Reliability engineering, from service objectives to operational judgment.
Relief after an interrupted night needs coverage and moved commitments. Then follow the recurring demand so the next week asks less of the same people.
Reliability work needs time, usable agreements and decisions that remove obstacles. Follow what a leader can change before, during and after an incident.
A service can accept every upload and still leave users without their files. Define success at the point users need the work to be done, then set a target you can act on.
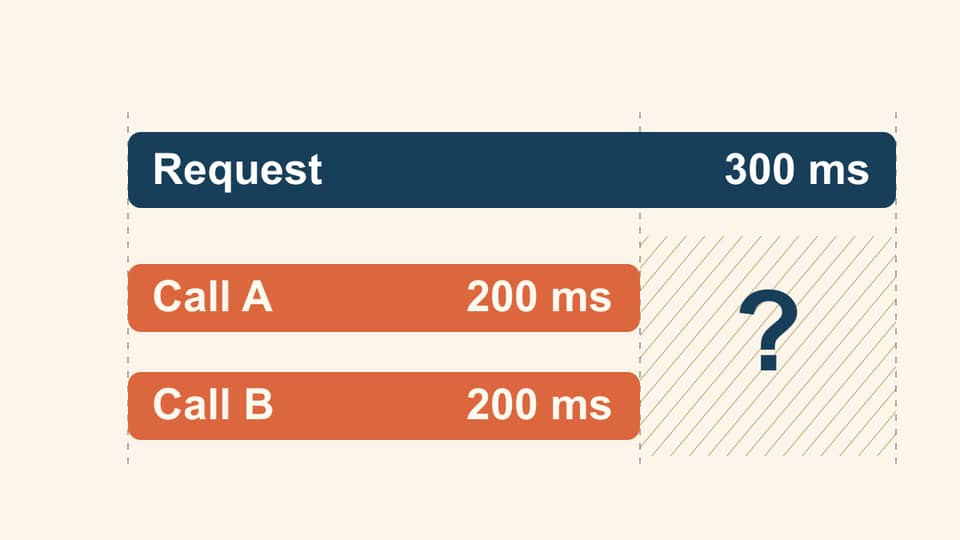
Read overlapping spans on a shared clock, compare like requests, and use the trace to choose what to check next.
Pages can fall while the same failures reach on-call through support. Check who found them, how long response took, and how much work the change saved.
Calculate how many bad requests an SLO allows, how much of that allowance remains, and how fast recent failures are using it.
Build a scorecard that shows what users received, where response lost time, and how much work it took to keep the service running.
Give Ubuntu a separate practice machine, confirm where your commands run and follow one small file through a shutdown and return.
A healthy website can still leave someone without their report. Define the whole useful outcome before choosing a measurement or an engineering fix.
Two exports are late, the API is healthy and the cause is unknown. Give responders a shared starting point without turning clues into conclusions.
The file is there, but ls says it is missing. Follow what Bash does to spaces, patterns and variables before the command receives them.
A job number arrives quickly; the report does not. Follow each handoff, its owner and the check that distinguishes a stored file from a usable result.